The pipeline works. The documentation doesn't.
Every data team has run into this at some point.
A pipeline gets built, someone documents it, and the documentation ends up in Confluence, a wiki, or a shared folder. A few months later, the pipeline has evolved. A new transform was added, a parameter changed, or someone tweaked the business logic. The pipeline is fine, but the documentation is describing an earlier version.
Most of the time nobody notices.
Until something breaks.
The engineer on call opens the documentation expecting it to explain what's happening, only to realize it no longer matches the pipeline. Before they can investigate the issue, they first have to work out what the pipeline actually does.
The same thing happens when a new developer joins the team. They read the documentation, then open Apache Hop anyway because that's where the real answers are. If the original author has moved on, understanding the project takes even longer.
Audits make the problem even more obvious. If someone asks how sensitive data moves through a pipeline, outdated documentation isn't much help. What matters is what's actually configured today, not what someone documented six months ago.
The obvious answer is to keep the documentation up to date but the reality is different.
Every pipeline change means updating another document, and that's rarely anyone's priority. Eventually the documentation falls behind, even on teams that genuinely try to keep it current.
Putki Autodoc
That led us to a simple question:
What if the documentation came directly from the pipeline instead of being written separately?
That's the idea behind Putki Autodoc.
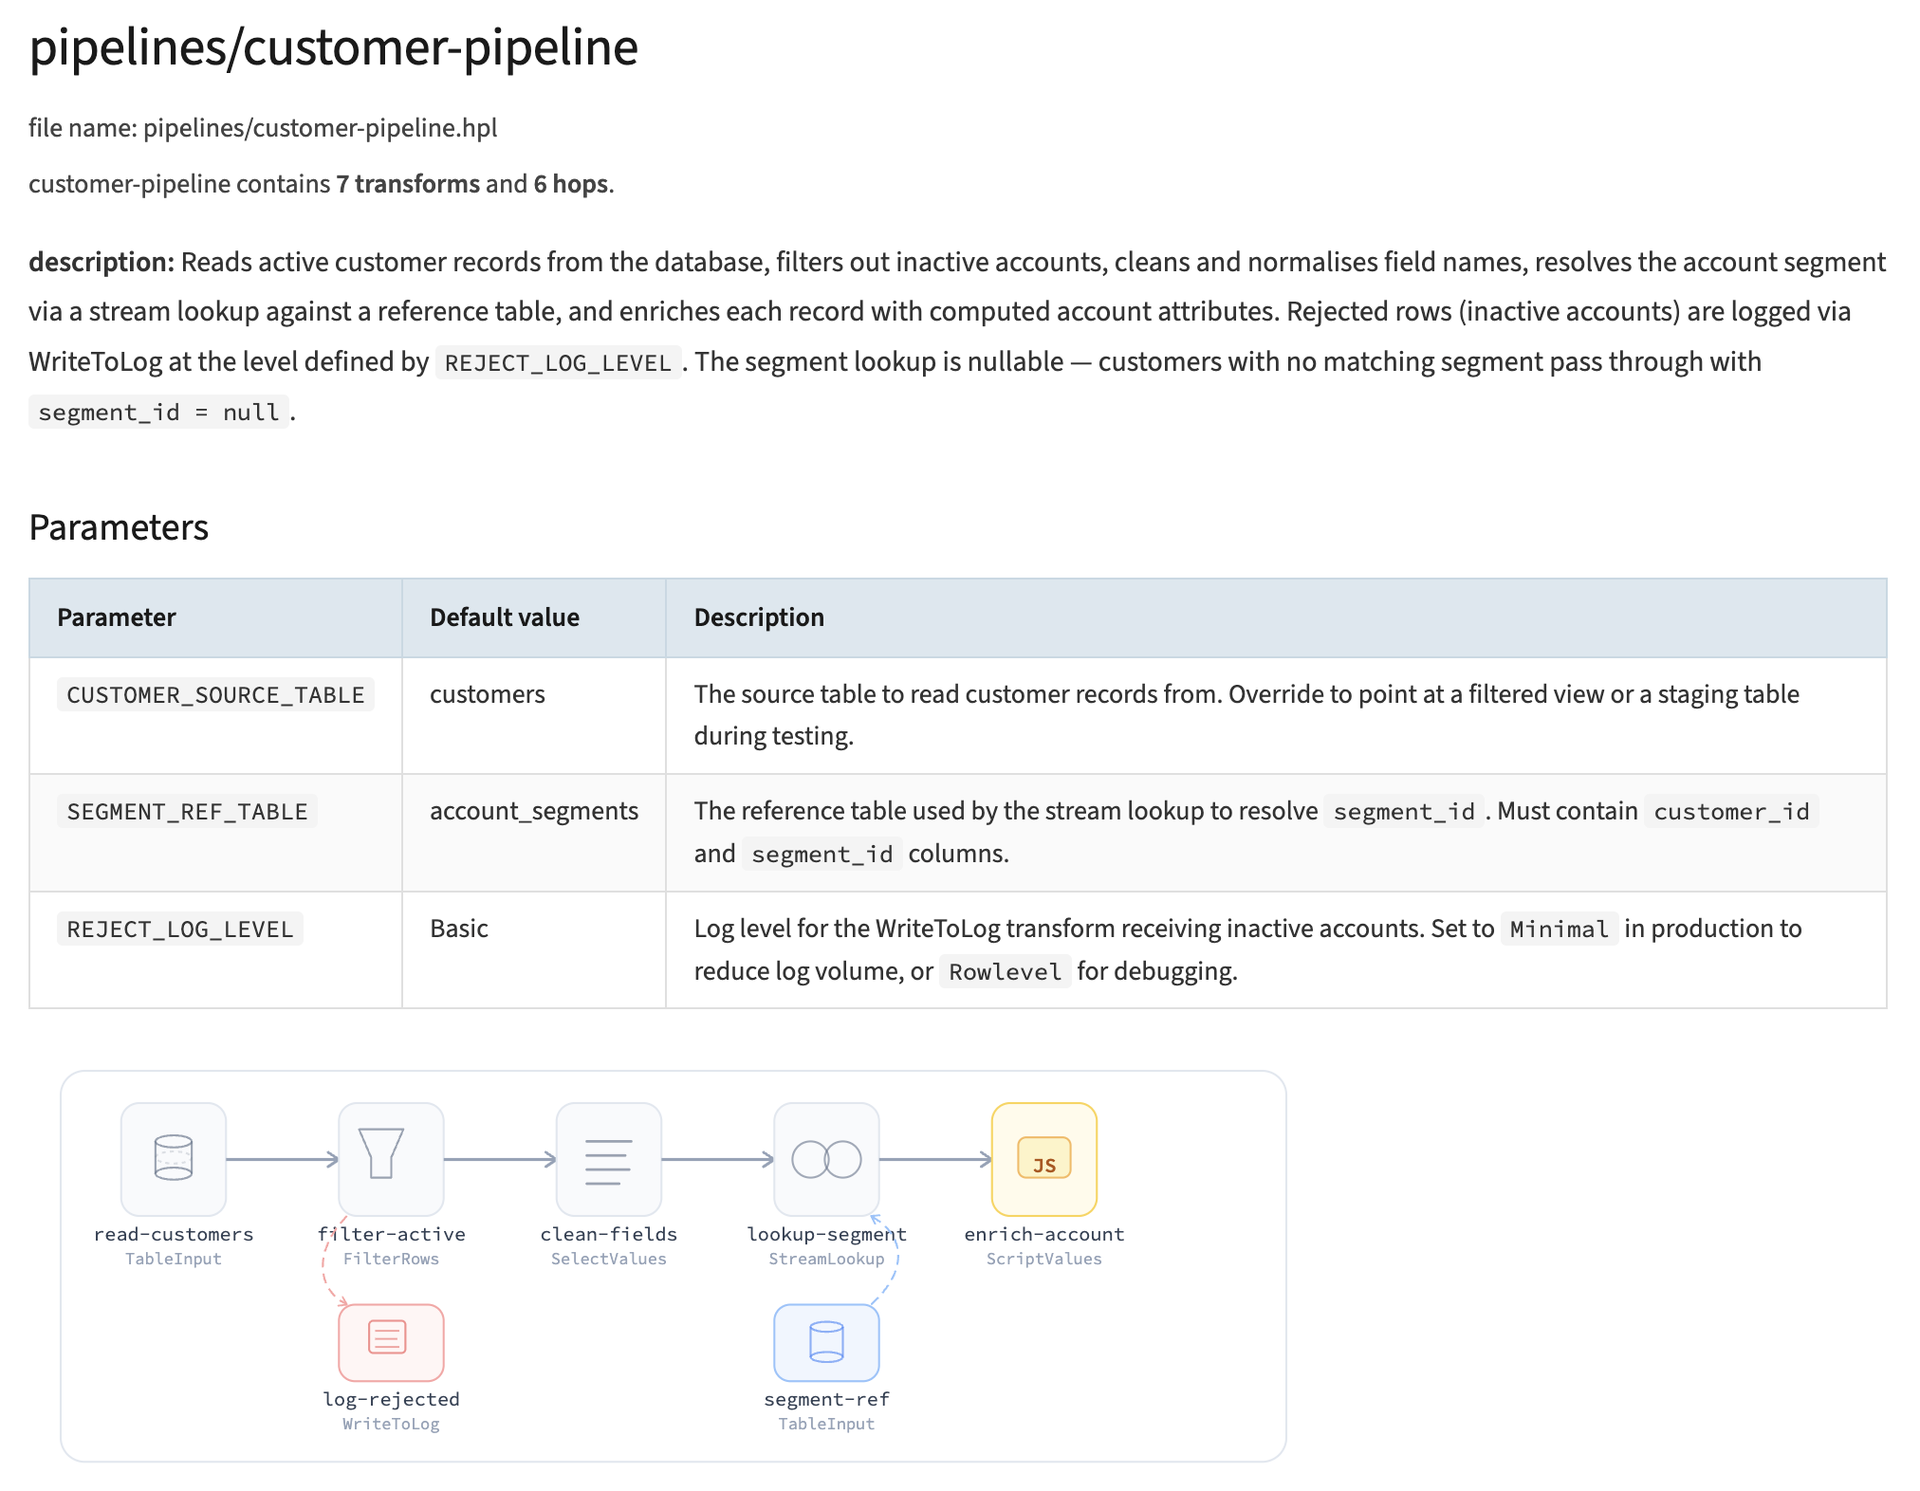
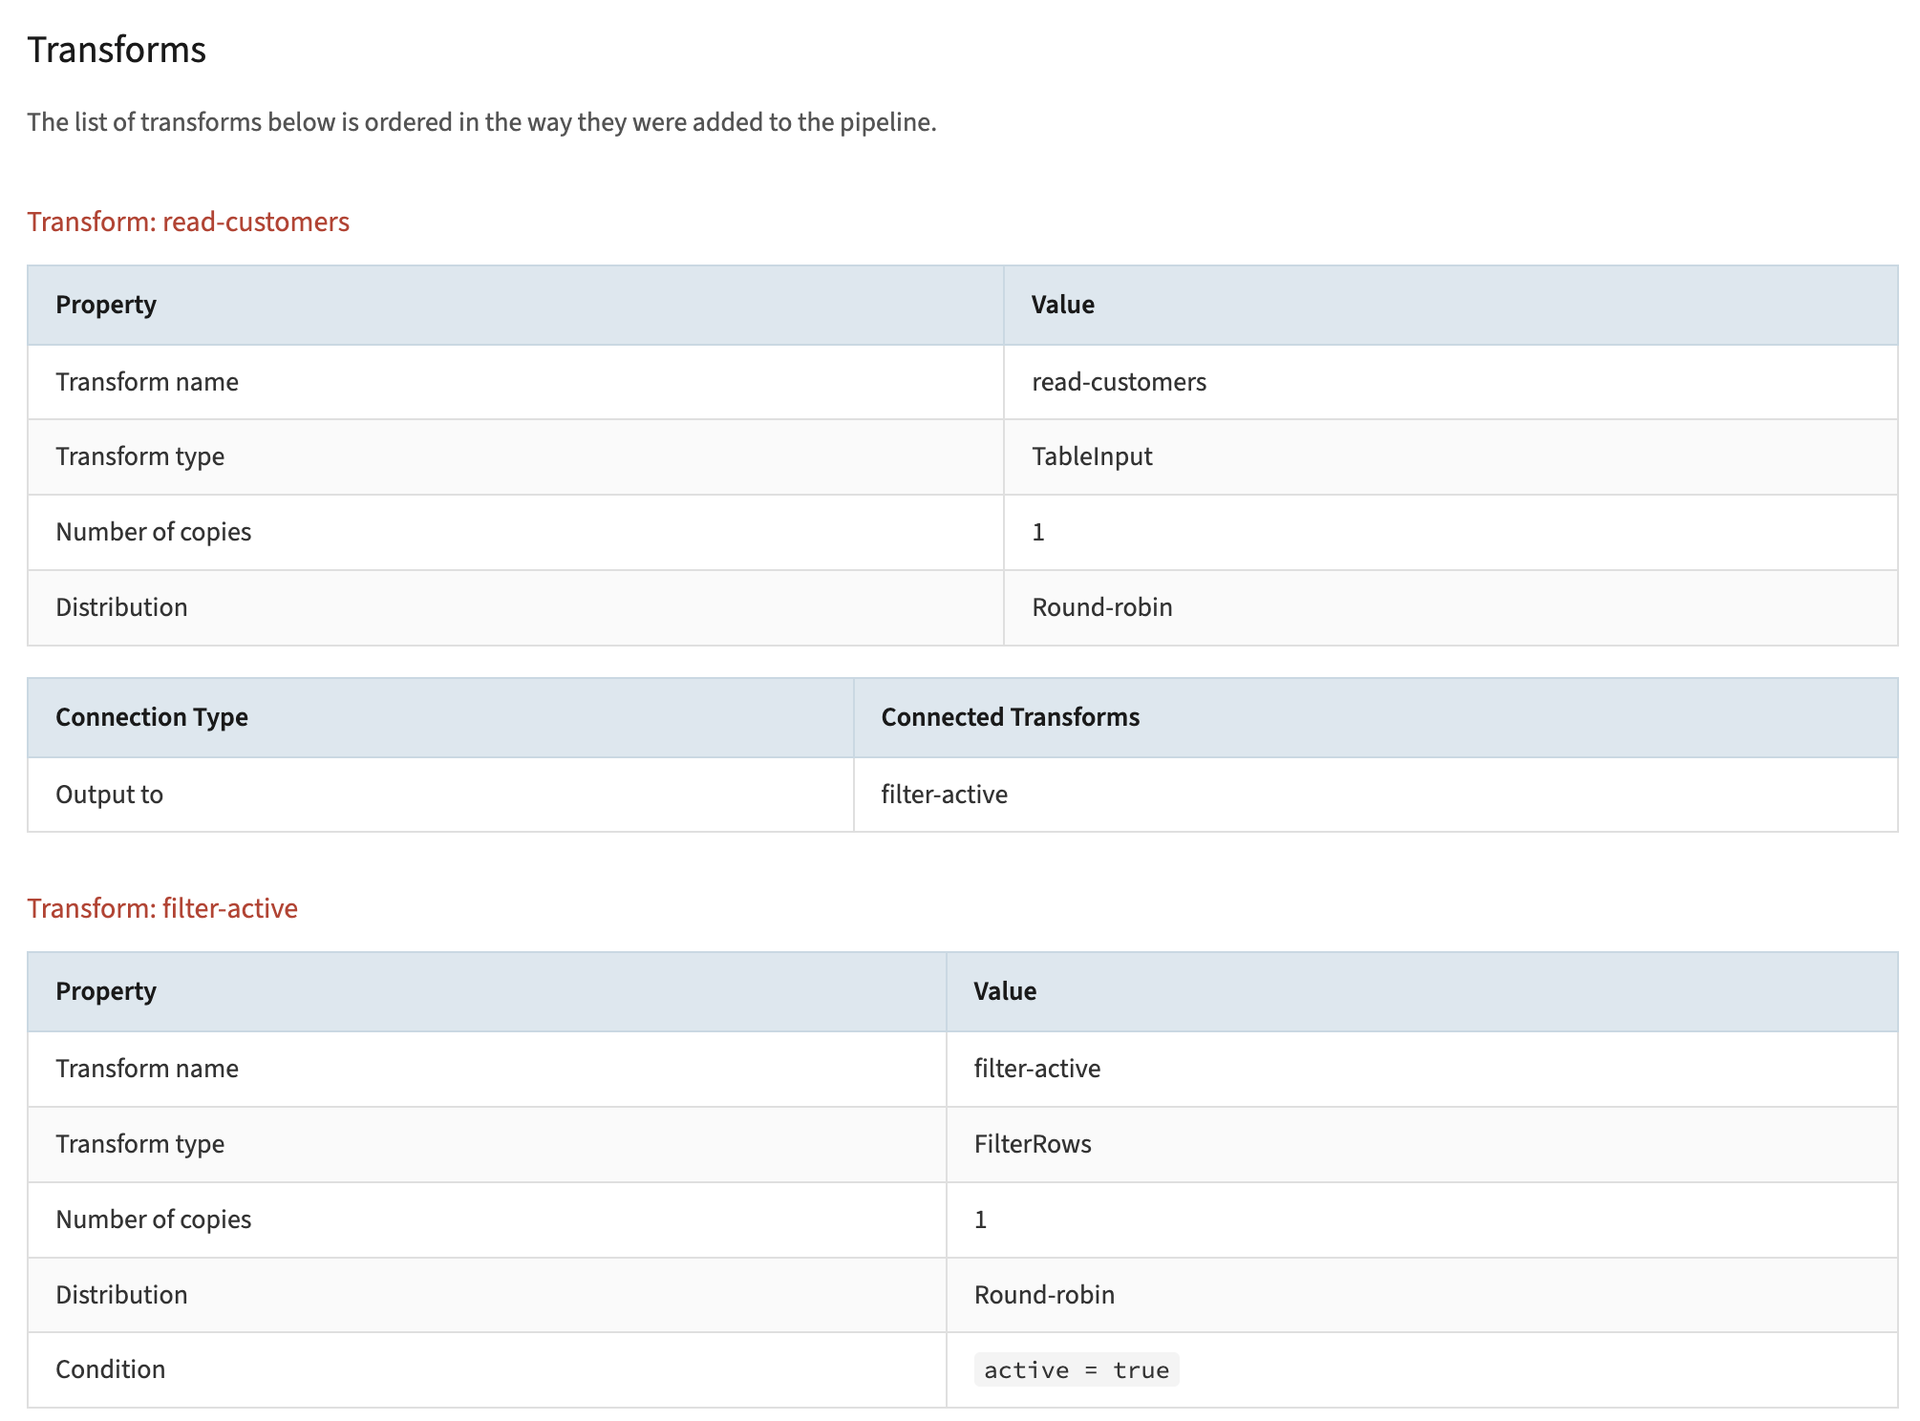
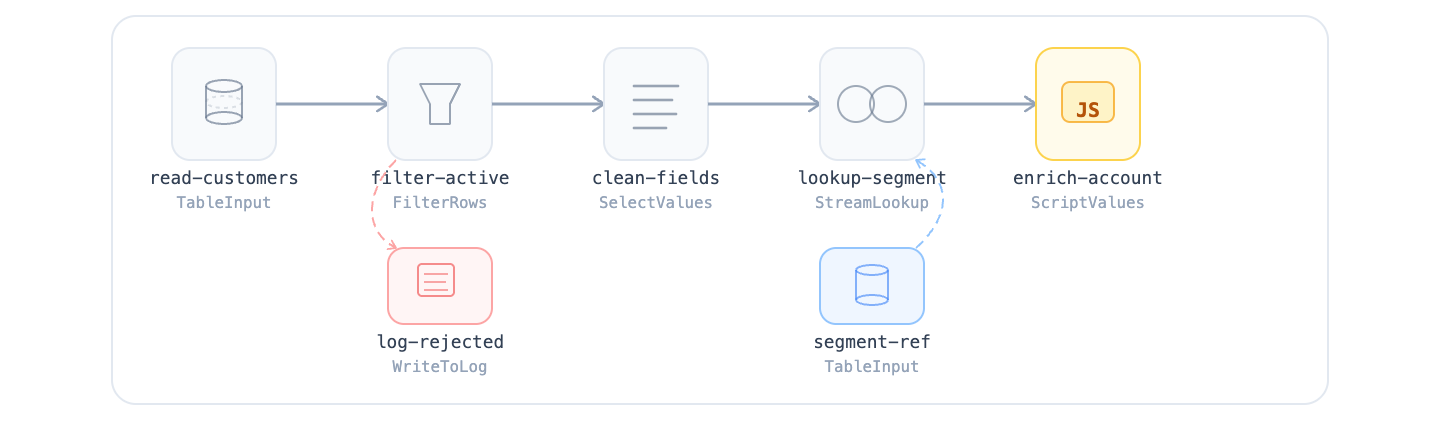
Autodoc reads Apache Hop metadata and generates technical documentation from the project itself. Instead of maintaining two versions of the same information, there's only one source of truth: the Hop project. The documentation simply reflects what's already there.
For the June 2026 release, we expanded the amount of information that gets captured. Generated documentation now includes much more of each transform's configuration, including parameters, field mappings, conditions, default values, and other settings that are often the first things engineers look for when troubleshooting or reviewing a pipeline.
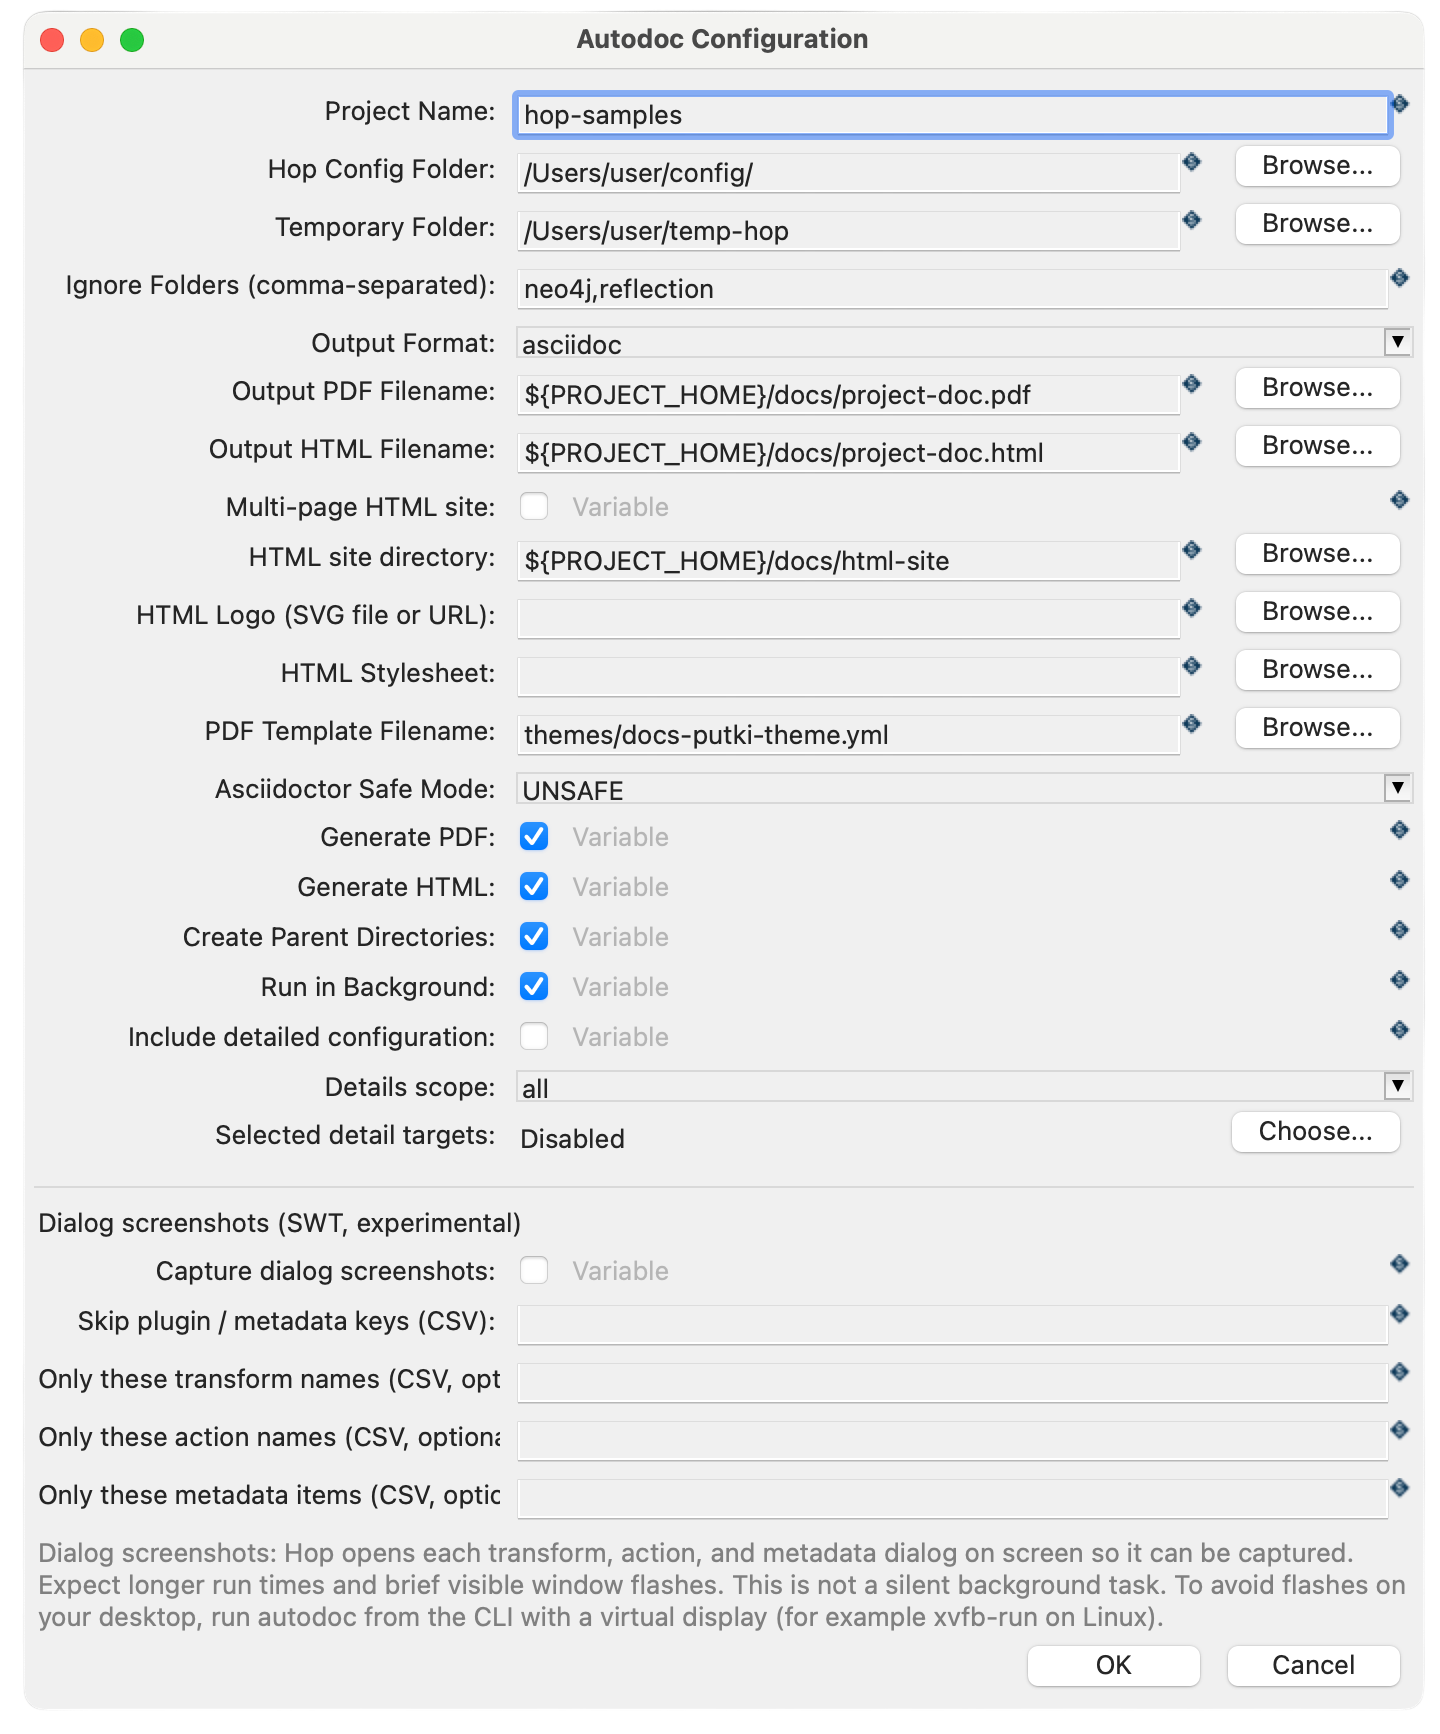
We also reworked how documentation is organized for larger projects. A single HTML page might work for five pipelines, but it quickly becomes difficult to navigate once a project grows. Documentation is now generated as separate pages for pipelines and workflows, making it much easier to browse, bookmark, and share.
Another feature we're particularly happy with is automatic screenshots of the actual Hop configuration. Sometimes a screenshot explains a transform faster than several paragraphs of text. Instead of describing every option, the documentation can simply show exactly what the engineer sees in Hop.
We're also adding support for themes, branding, custom fonts, and both HTML and PDF output, so the same documentation can be used internally or shared with customers, auditors, or other teams.
Autodoc isn't meant to replace architectural diagrams or the written explanations that describe why a system was designed a certain way. Engineers will always need those.
What it does remove is the repetitive work of documenting information that's already stored in the project.
When the metadata already knows how a pipeline is configured, there's little reason to write it all again by hand.
See Putki Autodoc in action
Technical documentation has always been one of those tasks everyone agrees is important but nobody enjoys maintaining.
Our goal with Putki Autodoc is straightforward: make documentation something that stays in sync automatically, because it's generated from the project itself.
When the pipeline changes, the documentation changes with it.